The Semantic Versioning Crisis: Engineering a Vector Schema Registry for Distributed RAG
Avoid silent failures in RAG by implementing a Vector Schema Registry. Learn how to manage embedding versioning, handle semantic drift, and enforce contracts in Laravel.
Changing Tires at 100 MPH: Zero-Downtime Schema Evolution in Vespa.ai
Master zero-downtime Vespa.ai schema migration using the shadow field backfill pattern and Visit API to update embedding dimensions without service interruption.
The Freshness Problem: Real-Time Vector Sync with Debezium and Kafka
Move RAG synchronization to the infrastructure level. Learn how Change Data Capture for Vector Search using Debezium and Kafka solves the dual-write problem and Update Storms.
Hybrid Retrieval 2.0: Tuning HNSW Parameters for pgvector at Scale
Optimize pgvector HNSW parameters for million-row vector databases. This guide covers m, ef_construction, and memory management for production-grade RAG.
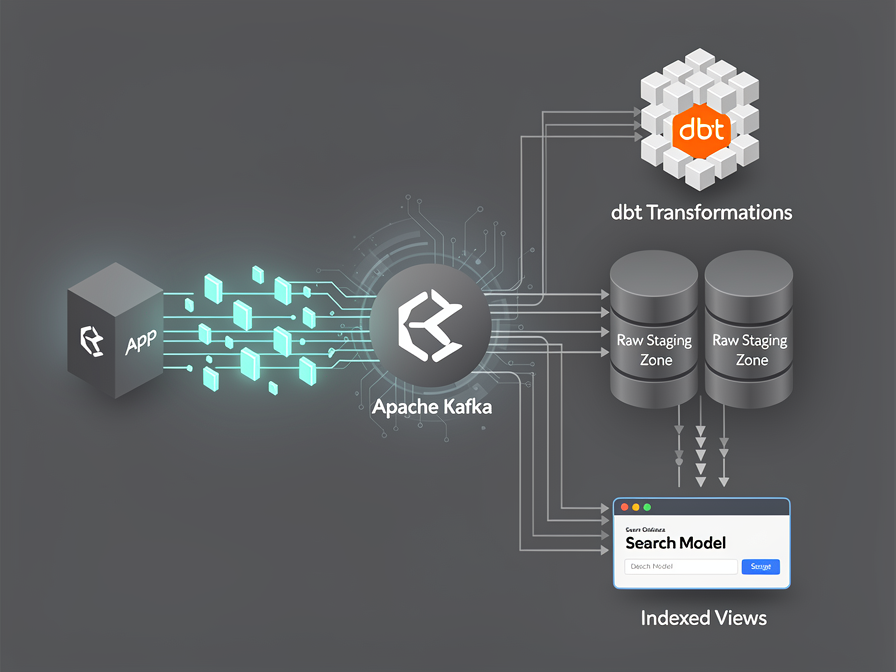
Event-Driven Ingestion: Scaling Search Pipelines with Kafka and dbt
An enterprise data architecture tutorial focused on building a high-throughput search ingestion pipeline. We demonstrate how to break up transactional database dependencies by using Apache Kafka for immutable event routing, coupled with dbt incremental models to manage near-real-time data transformations smoothly at scale.