The Fine-Tuning Trap: Why Your 2026 Roadmap Should Favor RAG Over Custom Models
Avoid weight rot by prioritizing RAG over fine-tuning. This guide explores the AI build vs buy decision matrix for 2026, focusing on context orchestration and architectural agility.
The Semantic Versioning Crisis: Engineering a Vector Schema Registry for Distributed RAG
Avoid silent failures in RAG by implementing a Vector Schema Registry. Learn how to manage embedding versioning, handle semantic drift, and enforce contracts in Laravel.
The Vector ETL: Offloading Document Chunking to dbt Python Models
Learn how to offload resource-heavy document chunking from application workers to your data warehouse using dbt Python models for RAG, ensuring lineage and scalability for AI pipelines.
Stop Hiring Prompt Engineers: The Case for Data Rigor in AI-Native Teams
Stop relying on prompt engineering to fix broken retrieval. Discover why context engineering and data pipeline rigor are the foundations of a modern AI engineering team structure.
The Semantic Data Warehouse: Modeling Vector-Relational Hybrids with dbt and Snowflake
Stop treating vectors as sidecars. Learn how to model embeddings directly in Snowflake using dbt to optimize RAG performance, handle model drift, and manage semantic-relational joins at scale.
The Freshness Problem: Real-Time Vector Sync with Debezium and Kafka
Move RAG synchronization to the infrastructure level. Learn how Change Data Capture for Vector Search using Debezium and Kafka solves the dual-write problem and Update Storms.
Graduating Your RAG Ingestion: When Laravel Queues Hit the Ceiling and Airflow Takes Over
Moving RAG ingestion from Laravel Horizon to Apache Airflow ensures resilience for complex vector pipelines. Learn to build a 'Signal-and-Poll' pattern for robust AI data orchestration.
The Silent Search Killer: Using dbt Tests to Guard Your Vector Ingestion Pipeline
Stop silent search degradation by implementing dbt macros to validate vector dimensions, L2 norms, and semantic drift across your ingestion pipelines.
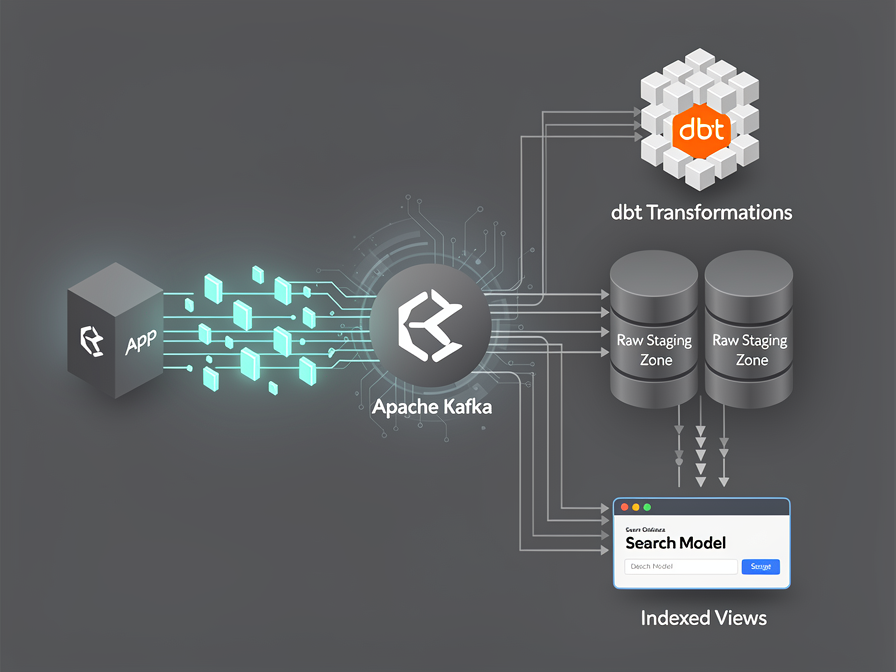
Event-Driven Ingestion: Scaling Search Pipelines with Kafka and dbt
An enterprise data architecture tutorial focused on building a high-throughput search ingestion pipeline. We demonstrate how to break up transactional database dependencies by using Apache Kafka for immutable event routing, coupled with dbt incremental models to manage near-real-time data transformations smoothly at scale.